

Making our design system useful beyond the design team
I turned our design system into an AI skill for PM exploration, then tested its boundaries and piloted it on a real product requirement.
- Role
- Sole product designer
- Audience
- Product managers
- Scope
- Skill design, evaluation, and maintenance
- Status
- Moderated PM pilot complete; iterating
Overview
I packaged our design system into an AI skill PMs could use to build mocks, with unapproved decisions clearly marked.
As IOU Financial’s sole designer, I held context PMs needed: how components behave, which patterns fit, and which product decisions were still open. I packaged the system’s visual rules, component behavior, and screen recipes into an AI skill an agent could use to build mocks.
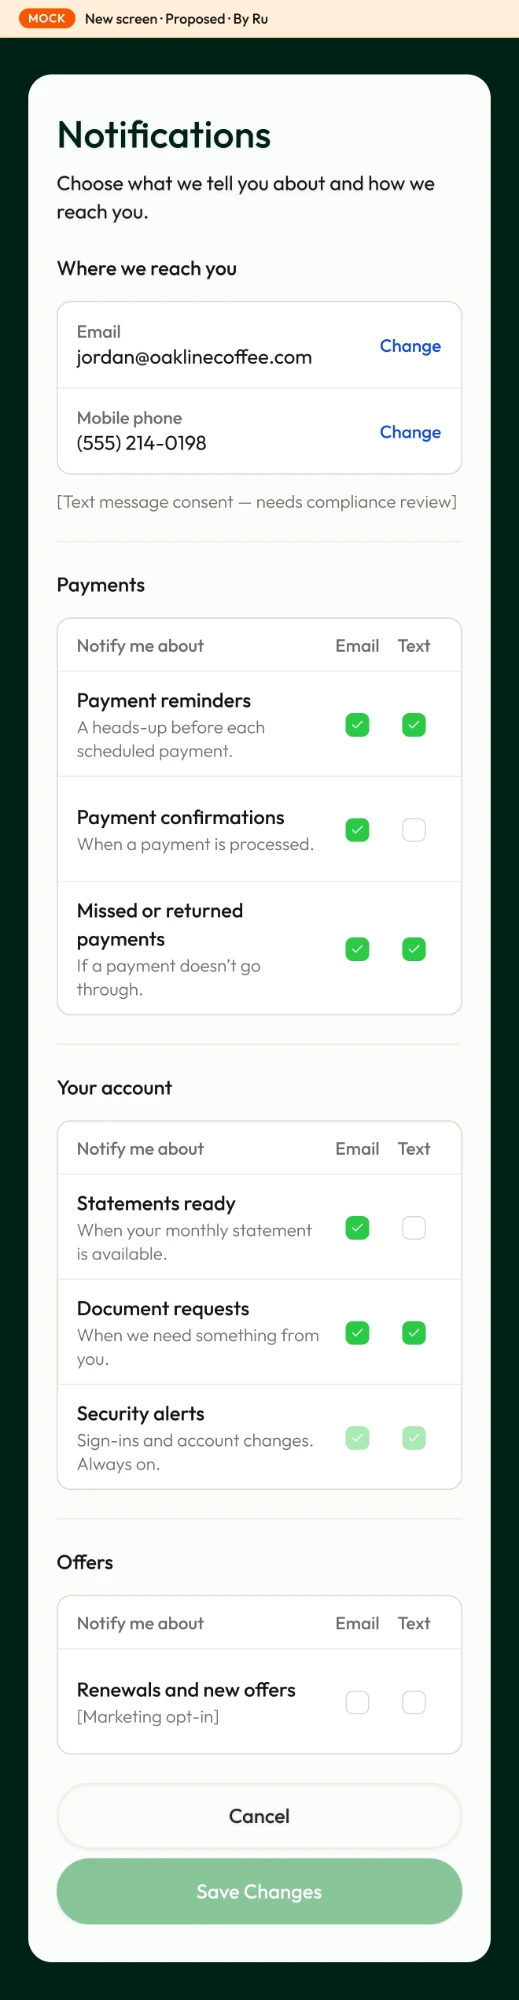
Keep proposals recognizable. Outputs carry a mock label, creator, and date; unapproved amounts, legal copy, and policy details remain placeholders for review.
Failure and Fix
The agent had the components to build a screen, but not the product decisions behind it.
Of eight tasks tested in fresh sessions, one requested an undefined income-verification step. The agent invented fields, amounts, and legal copy that looked plausible.
A stricter instruction still allowed a generic form. I listed supported steps and ruled out generic forms outside them. Across five reworded requests in fresh sessions, it stopped and asked.
The boundary was clearer. Next, I needed to support exploration beyond it.
Opening It Up
The boundary worked, but blocked what PMs needed next: exploring beyond the loan application.
PMs wanted to explore new experiences with our components. Restricting the skill to existing application steps limited the work it was meant to support.
I tried allowing drafts only when requested, but useful output depended on knowing the right prompt. I made labeled mocks the default, with proposed decisions flagged and unapproved details left open.
Existing screens follow recipes. Proposed changes explain rule conflicts. New experiences use system components and are labeled as new to the system.
I tested this expanded approach on a checkout flow using our team’s brainstorm transcript, with both Opus and Sonnet. The outputs reflected the discussion while leaving unapproved requirements and timelines as placeholders. The earlier five tests established stop-and-ask behavior; they didn’t validate this expanded approach.
PM Pilot
A PM turned an ownership requirement into a proposed co-owner flow, giving the team something concrete to discuss.
In a moderated pilot, a PM started by adding ownership percentage to an existing screen. That raised a larger question: how would a co-owner join the application?
The agent asked about invitations and whether the primary applicant could submit first. The PM supplied the proposed behavior, developing the idea into connected applicant and co-owner paths.
She then shared the mock with the head of product during the session. The pilot showed how the skill could support product exploration and discussion; independent use remains untested.
Keeping It Current
Testing exposed contradictions in my guidance. The pilot showed how it could also fall behind the designs.
The guide said radio pills should “fill the row,” while the code specified 148px. Testing surfaced a contradiction I could resolve in the source guidance. Later, the pilot reproduced an outdated website/social field: its recipe no longer matched Figma.
Add a scheduled Figma check. A follow-up run identified six updates and screen renames, then prepared revised guidance for review. Applying and publishing it remained a separate step.
Results
Testing clarified the skill’s boundaries, a PM pilot put it to use, and a Figma check exposed outdated guidance.
The PM used the mock to work through an idea before writing a ticket and bring it into discussion with the head of product. The pilot also exposed a maintenance gap and led to a workflow for detecting changes in Figma.
The evidence so far is agent evaluations and one moderated PM pilot. Continued independent use, accuracy across more tasks, and time savings remain to be assessed.
For the product
A requirement became a proposal
- A PM brought a real requirement
- Mocked it as a proposed flow
- Took it to the head of product
For the system
A gap became a routine
- The pilot showed the skill could fall behind
- Added a weekday Figma check
- Updates wait for my review
Reflection
What I learned
A polished screen can still be wrong.
The agent used our components while inventing product decisions. Visual consistency alone couldn’t tell a reviewer what was approved; labels and placeholders needed to make those boundaries visible.
Useful exploration shouldn’t depend on the right prompt.
Requiring PMs to ask for a draft added friction. Making labeled mocks the default let them start with an idea, and the pilot showed how seeing it could help a PM work out what she wanted.
Testing the agent also tested my system.
The conflicting radio-pill guidance and outdated field exposed two ways the skill could mislead: ambiguity and drift. Maintaining the skill meant resolving contradictions and checking it against the source designs.